
Vector Database Architecture for AI Products
Design vector database architecture for RAG and AI search: embeddings, indexing, retrieval, and access control. Built to scale with predictable costs.
What You Need to Know
Vector databases are the backbone of RAG: they store embeddings so your AI can retrieve the right context quickly.
We design the full retrieval system: chunking strategy, embeddings model choice, indexing, filtering, and relevance tuning for your domain.
We also engineer governance: document permissions, tenant isolation, audit logs, and safe query paths so private data stays private.
The outcome is a retrieval layer that improves answer quality while keeping latency and cost under control.
What You'll Get
RAG-ready vector architecture
Chunking, embeddings, indexing, and retrieval design.
Security + access controls
Tenant isolation, filters, and safe data boundaries.
Relevance tuning plan
Evaluation and iteration framework for retrieval quality.
Provider selection guidance
Choose the right vector store for your scale and budget.
Ingestion + refresh strategy
Sync pipelines, backfills, and doc lifecycle handling.
Observability for retrieval
Track hit rates, latency, and failure modes over time.
Planning a build like this?
Book a free 30-minute strategy call with Diyanshu Patel, our CEO. We use it to understand your idea, goals and requirements, then follow up with a timeline and a fixed-price proposal.
Book a free 30-minute callFAQ
What does a vector database actually do in an AI product?
It stores content as numerical embeddings (representations of meaning, not just keywords) and finds the most semantically similar entries to a query. This is the retrieval half of retrieval-augmented generation: it's how an AI product finds the right chunk of your documentation or data to ground an answer in.
Which vector database should I use: Pinecone, Weaviate, or pgvector?
Pinecone and Weaviate are managed, purpose-built vector databases with strong performance at scale but add a separate service to operate. pgvector runs inside Postgres, which is simpler if you're already using Postgres (e.g. via Supabase) and don't yet need vector-database-specific scale; migrating later is straightforward if usage grows past what pgvector handles well.
How much does vector database architecture cost to set up?
Typically $2,000-$5,000 as part of a larger AI MVP build (embedding pipeline, indexing strategy, retrieval logic), plus ongoing infrastructure costs of roughly $50/month for early-stage usage, scaling with data volume and query rate.
What goes wrong if vector database architecture is designed poorly?
Poor chunking strategy returns irrelevant context to the model, causing confident wrong answers. Missing access control lets one tenant's retrieval leak into another's results in a multi-tenant product. No reranking step means the most relevant result isn't always what gets retrieved first, degrading answer quality even when the right data exists in the index.
Trusted by Global Companies Building AI Products
We've helped startups and enterprises worldwide transform their AI ideas into production-ready MVPs in 2–3 weeks. From fintech platforms to AI assistants, our global MVP development services have launched 18+ AI products serving users across the US, Europe, and Asia.
Portfolio: AI Products Built for Global Startups
From content platforms and AI assistants to analytics dashboards and fintech solutions: see how we've transformed ideas into production-ready MVPs in 2-3 weeks across diverse industries. Each product here is one our team worked on.
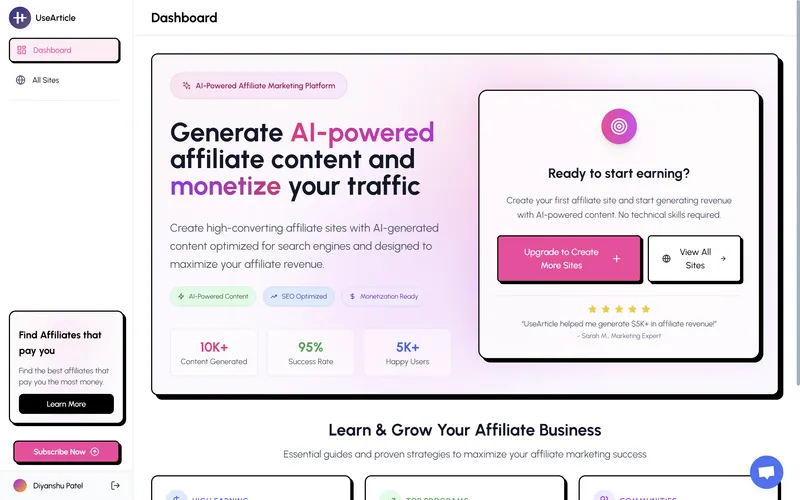
UseArticle
AI-powered content creation and management platform that helps teams produce high-quality articles at scale.
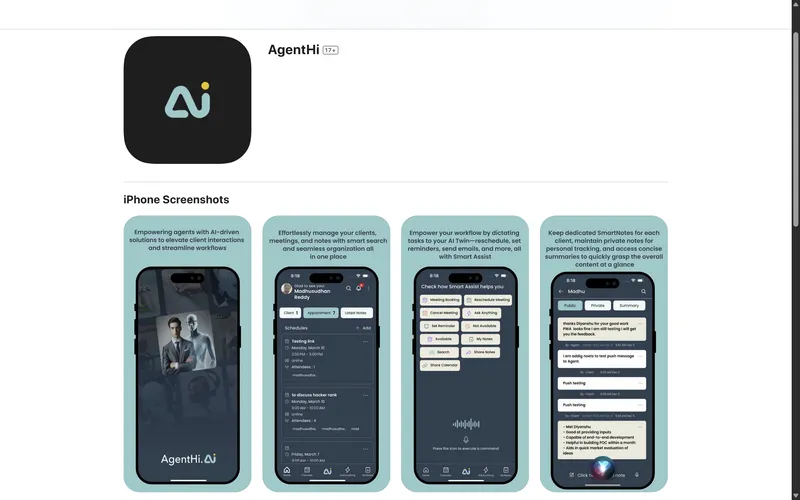
AgentHi
Intelligent virtual assistant that streamlines customer support and automates routine business tasks.
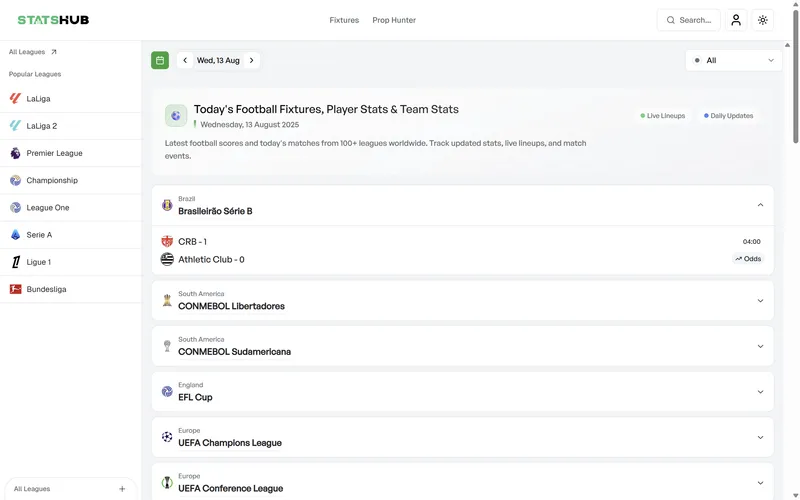
StatsHub
Comprehensive analytics dashboard providing real-time insights and data visualization for businesses.
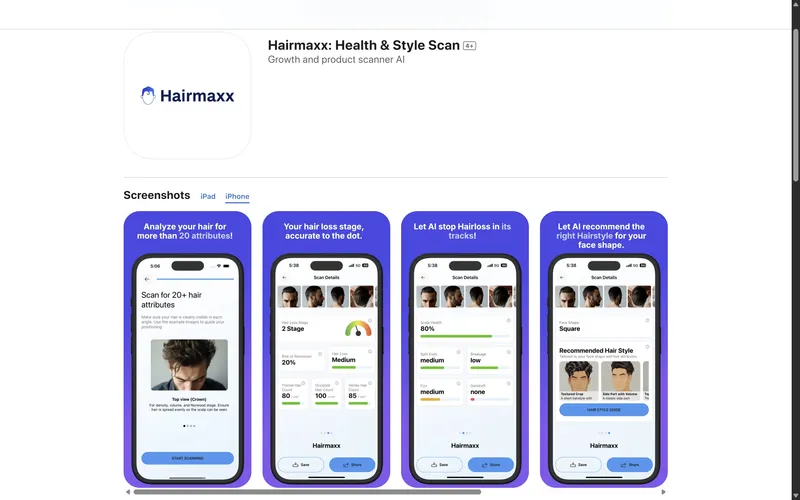
Harimaxx
Personal fitness companion with AI-driven workout plans and nutrition tracking for optimal health.
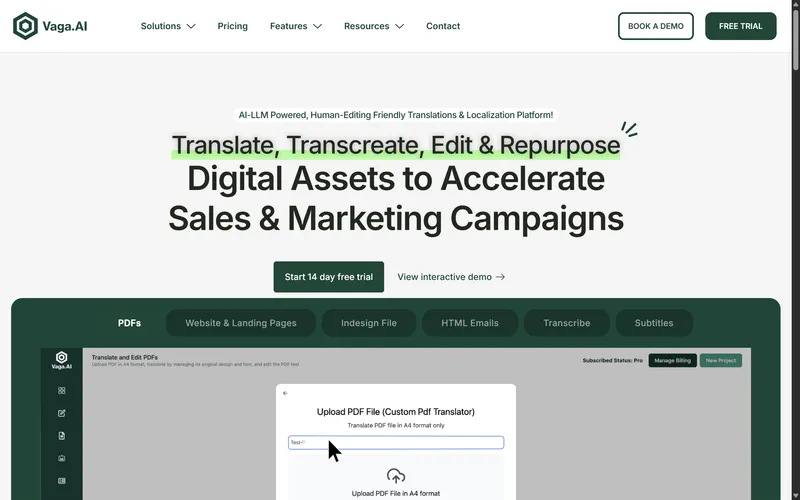
Vaga
Smart travel planning app that curates personalized itineraries and local experiences.
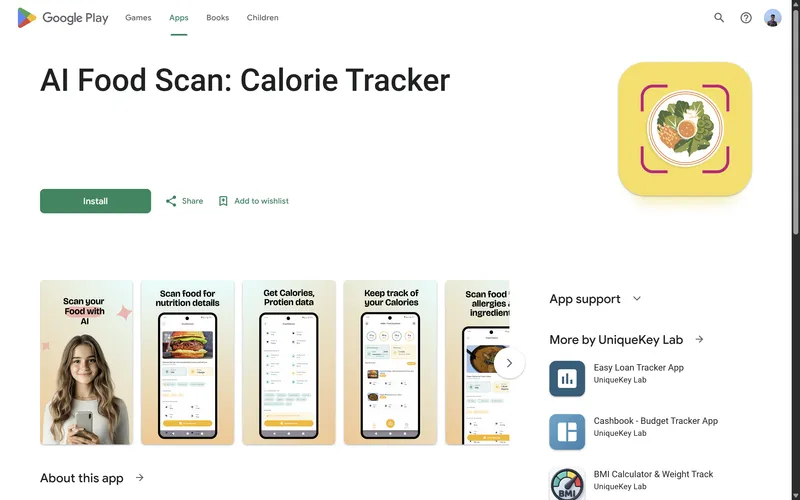
FoodScan
Nutrition analysis app that scans food items and provides detailed nutritional information instantly.
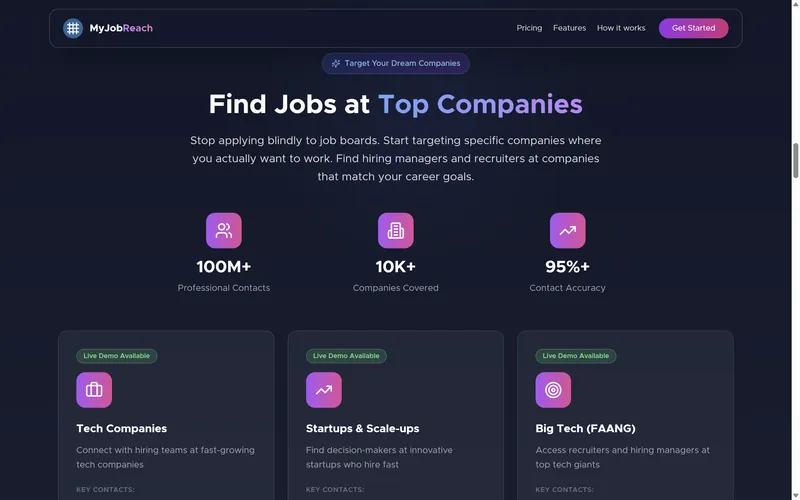
MyJobReach
Job matching platform connecting talented professionals with their dream opportunities.
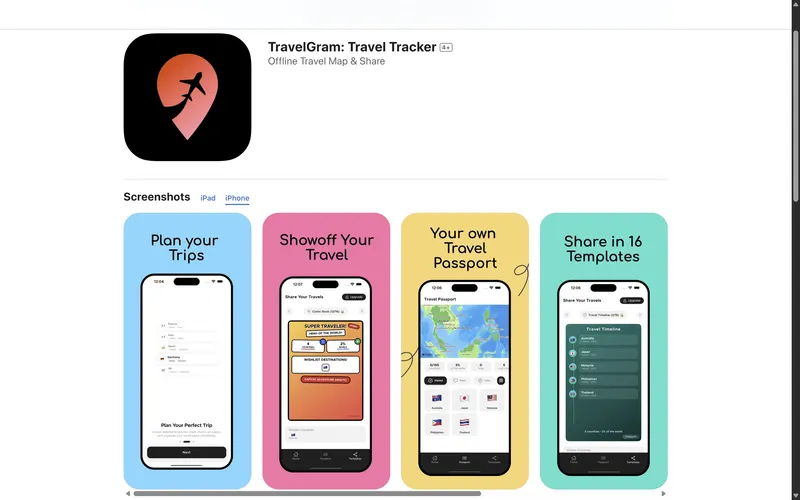
TravelGram
Social platform for travelers to share experiences, discover destinations, and connect globally.
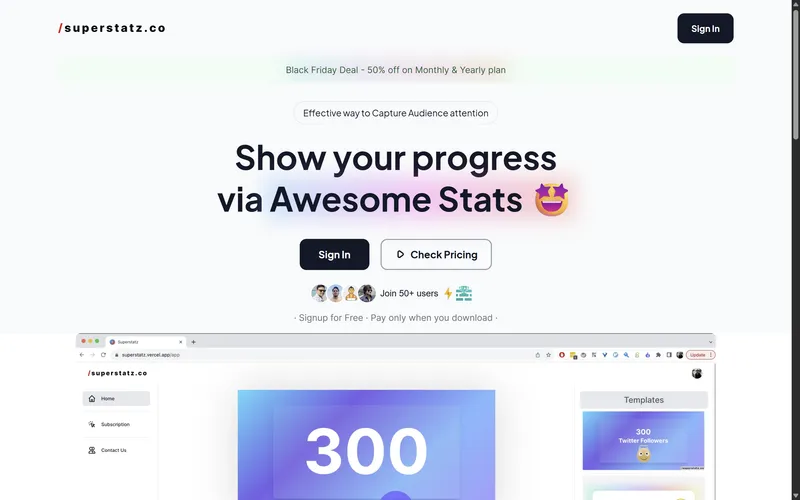
SuperStatz
Advanced sports statistics platform delivering in-depth analysis and performance metrics.
Cashbook
Simple expense tracking and budgeting app that helps users manage their finances effortlessly.
TypeFast
Typing speed improvement platform with gamified lessons and real-time performance tracking.
Easy Loan
Streamlined loan management system that simplifies borrowing and lending processes.
Explore Related Content
Discover more services, case studies, and insights
Next.js MVP Development Services
Build a fast, SEO-friendly MVP on Next.js with clean architecture, analytics, and production deployment. Launch in weeks with code your team can extend.
Vercel Hosting for Next.js MVPs
Deploy and scale Next.js MVPs on Vercel with best practices for performance, previews, rollbacks, and analytics. Fast iteration with production reliability.
Voice AI Development Cost in 2026
What voice AI actually costs to build and run: speech-to-text, LLM, and text-to-speech per minute, plus the latency work that decides whether it feels usable.
Web3 MVP Development Services
Ship a Web3 MVP in 2-3 weeks: tested smart contracts, dApp frontend, and wallet auth on a fixed-price model. From $5k-$25k vs slow blockchain agencies.
AI-Powered MVP Development
Launch a production-ready AI MVP in just 2-3 weeks. Our team blends rapid prototyping with enterprise-grade AI/ML engineering to validate your idea, attract investors, and win early customers.
Integrate AI into Existing Software
Smoothly integrate AI capabilities into your existing software systems. We enhance your current applications with intelligent features, automation, and AI-powered insights while maintaining system stability.
How AI Agencies Ensure Quality at Speed
How top AI development agencies ship quality, scalable products in 2-3 weeks: senior engineers, AI-assisted workflows with human review, production-grade architecture, and automated testing under real deadlines.
Selecting an AI Development Partner
How enterprise teams should evaluate an AI development partner: technical AI depth, SOC 2/GDPR/HIPAA compliance, security and data governance, legacy integration, scalable architecture, SLAs, and procurement fit: with a checklist and vendor questions.
AI Job Matching MVP Cuts Time-to-Hire to 38 Hrs
A purpose-built embedding pipeline using e5-large + a domain re-ranker, hybrid search over Postgres pgvector, multi-step matching agents that score by role rather than keywords, and a Next.js recruiter dashboard that drafts personalized outreach in the recruiter's voice.
AI E-commerce Personalization Lifts Add-to-Cart Rate 34%
SpeedMVPs built a real-time AI personalization engine on their existing Next.js storefront backed by pgvector on Supabase for product and user embeddings. A collaborative-filtering model trained on 18 months of order and clickstream data was deployed via a FastAPI microservice, surfacing ranked recommendations per user in under 80ms. Personalized search reranking was layered on top of their existing Algolia index using a lightweight LLM-based intent classifier that rerouted ambiguous queries to semantically similar in-stock products.
Ready to Build Your MVP?
Schedule a complimentary strategy session. Transform your concept into a market-ready MVP within 2-3 weeks. Partner with us to accelerate your product launch and scale your startup globally.
The call is 30 minutes with Diyanshu Patel, our CEO and co-founder. Afterwards you get a written proposal with timeline, pricing and development plan.
Calendar not loading? Open the booking page or email diyanshu@speedmvps.com.