
Model Selection & Training
YOLO, Detectron2, or task-specific architectures fine-tuned and benchmarked on your data.
Object detection locates and classifies objects within images and video: bounding boxes, class labels, and confidence scores, in real time or in batch. We build the full pipeline, from dataset labeling through model training to deployment on cloud GPUs or edge hardware, tuned to your specific accuracy and latency requirements.
Computer vision that locates, classifies, and tracks objects in images and video
YOLO, Detectron2, or task-specific architectures fine-tuned and benchmarked on your data.
Live detection pipelines running at target frame rates with object tracking across frames.
High-throughput detection over image archives or stored video where latency isn't the constraint.
Models exported to ONNX/TensorRT and optimized for Jetson, Coral, or mobile hardware.
Annotation tooling, active learning, and augmentation to build and grow your training set.
Quantization, pruning, and threshold tuning to hit your specific speed and accuracy targets.
Defect and anomaly detection pipelines for production-line or visual QA use cases.
A 60fps security feed and an overnight batch job need different architectures; we benchmark against your actual constraint, not a leaderboard number.
Model accuracy is bounded by data quality. We build the labeling pipeline and augmentation strategy alongside the model, not as an afterthought.
We export the same model family to ONNX/TensorRT for on-device inference or serve it from a GPU cluster, depending on your latency and connectivity constraints.
mAP numbers from a paper don't tell you what happens on your target device at your frame rate; we test on the actual hardware.
A 60fps security feed and an overnight batch job need different architectures; we benchmark against your actual constraint, not a leaderboard number.
Model accuracy is bounded by data quality. We build the labeling pipeline and augmentation strategy alongside the model, not as an afterthought.
We export the same model family to ONNX/TensorRT for on-device inference or serve it from a GPU cluster, depending on your latency and connectivity constraints.
mAP numbers from a paper don't tell you what happens on your target device at your frame rate; we test on the actual hardware.
We've helped startups and enterprises worldwide transform their AI ideas into production-ready MVPs in 2–3 weeks. From fintech platforms to AI assistants, our global MVP development services have launched 18+ AI products serving users across the US, Europe, and Asia.
From content platforms and AI assistants to analytics dashboards and fintech solutions: see how we've transformed ideas into production-ready MVPs in 2-3 weeks across diverse industries. Each product launched successfully, serving users globally.
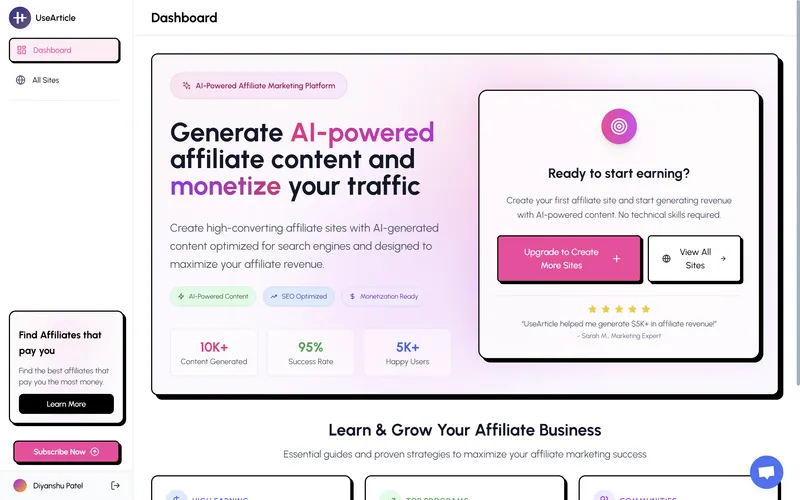
AI-powered content creation and management platform that helps teams produce high-quality articles at scale.
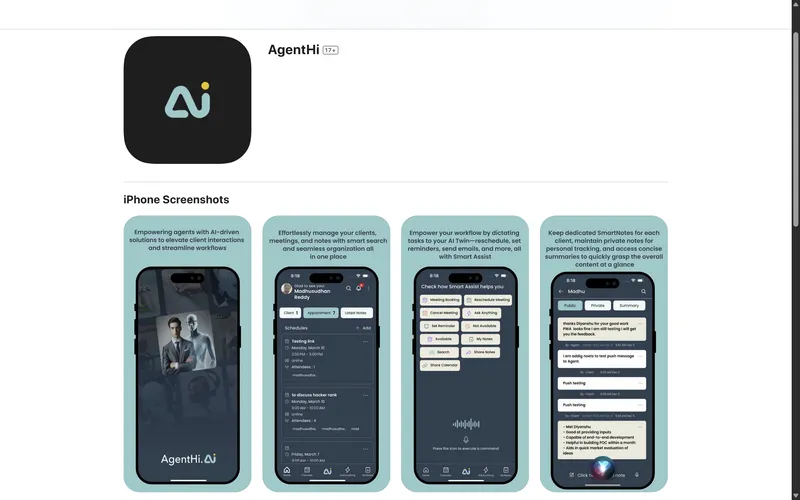
Intelligent virtual assistant that streamlines customer support and automates routine business tasks.
Comprehensive analytics dashboard providing real-time insights and data visualization for businesses.
Personal fitness companion with AI-driven workout plans and nutrition tracking for optimal health.
Smart travel planning app that curates personalized itineraries and local experiences.
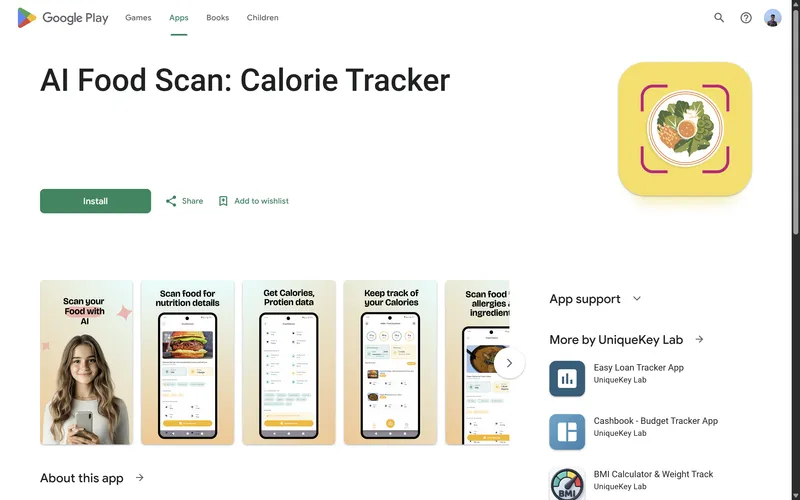
Nutrition analysis app that scans food items and provides detailed nutritional information instantly.
Job matching platform connecting talented professionals with their dream opportunities.
Social platform for travelers to share experiences, discover destinations, and connect globally.
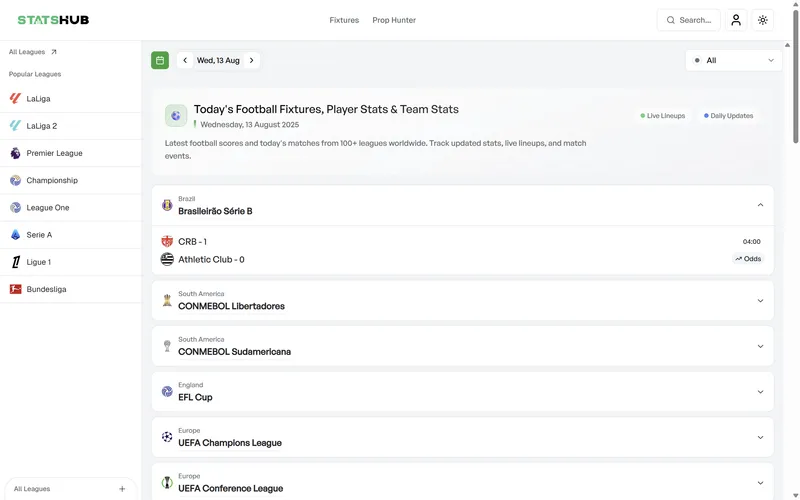
Advanced sports statistics platform delivering in-depth analysis and performance metrics.
Simple expense tracking and budgeting app that helps users manage their finances effortlessly.
Typing speed improvement platform with gamified lessons and real-time performance tracking.
Streamlined loan management system that simplifies borrowing and lending processes.
Discover more services, technologies, case studies, and resources
Edge AI deployment runs trained models directly on-device, on phones, embedded boards, or IoT hardware, instead of a cloud server, trading some model size and accuracy for offline operation, lower latency, and no per-inference cloud cost. The engineering problem is different from cloud-hosted AI work: it's quantization, format conversion, and fitting a model's memory and compute footprint into hardware measured in megabytes and milliwatts, not GPU-hours.
AI MVP development services for funded startups and enterprise teams in the US, UK, Canada, Australia, and the EU. As an AI MVP development company, we build custom, AI-powered MVPs that ship production-ready, with real LLM integration and full code ownership, priced in USD and delivered in 2-3 weeks.
An SRE-style reliability hardening add-on for products that already have real traffic: monitoring, alerting, autoscaling, backups, and incident runbooks so the system stays up and recoverable under load. This is ongoing operational practice, not the one-time platform setup covered by Next.js Deployment and DevOps, and it's infrastructure-focused rather than feature-focused, unlike Post-MVP Iteration. It also isn't the full multi-region, compliance-driven program covered by Enterprise-Grade Engineering: this add-on is day-to-day reliability practice for a single-region product that needs to stay up, not a SOC 2 or HIPAA rebuild.
Your MVP launched. Now build what users actually need. We run structured iteration cycles, 2-week sprints that ship improvements, new features, and AI quality upgrades based on real usage data.
Schedule a complimentary strategy session. Transform your concept into a market-ready MVP within 2-3 weeks. Partner with us to accelerate your product launch and scale your startup globally.