
Model Quantization & Pruning
Compress trained models to fit on-device memory and compute budgets with measured accuracy tradeoffs.
Edge AI deployment runs trained models directly on-device, on phones, embedded boards, or IoT hardware, instead of a cloud server, trading some model size and accuracy for offline operation, lower latency, and no per-inference cloud cost. The engineering problem is different from cloud-hosted AI work: it's quantization, format conversion, and fitting a model's memory and compute footprint into hardware measured in megabytes and milliwatts, not GPU-hours.
Getting trained models to actually run on constrained hardware
Compress trained models to fit on-device memory and compute budgets with measured accuracy tradeoffs.
Core ML for iOS and TensorFlow Lite for Android, integrated with hardware acceleration where available.
ONNX Runtime and platform-specific runtimes for Jetson, Coral, and other embedded boards.
Fully on-device inference paths with no network dependency, plus sync logic for when connectivity returns.
Tuning model size, batching, and duty cycling against real device latency and battery budgets.
Ship new model versions to a device fleet without a full app store release cycle.
A model that runs fast on a laptop can be unusably slow on the actual phone or embedded board it's shipping to. We measure on the real target device before calling anything done.
Quantization and pruning cost some accuracy. We measure exactly how much, on your validation set, so you're making an informed tradeoff instead of guessing.
Models drift and improve. We ship a way to update the on-device model without forcing a full app store release for every iteration.
When the requirement is 'must work with no signal,' that constrains the whole pipeline, not just the model. We design for it from the start.
A model that runs fast on a laptop can be unusably slow on the actual phone or embedded board it's shipping to. We measure on the real target device before calling anything done.
Quantization and pruning cost some accuracy. We measure exactly how much, on your validation set, so you're making an informed tradeoff instead of guessing.
Models drift and improve. We ship a way to update the on-device model without forcing a full app store release for every iteration.
When the requirement is 'must work with no signal,' that constrains the whole pipeline, not just the model. We design for it from the start.
We've helped startups and enterprises worldwide transform their AI ideas into production-ready MVPs in 2–3 weeks. From fintech platforms to AI assistants, our global MVP development services have launched 18+ AI products serving users across the US, Europe, and Asia.
From content platforms and AI assistants to analytics dashboards and fintech solutions: see how we've transformed ideas into production-ready MVPs in 2-3 weeks across diverse industries. Each product launched successfully, serving users globally.
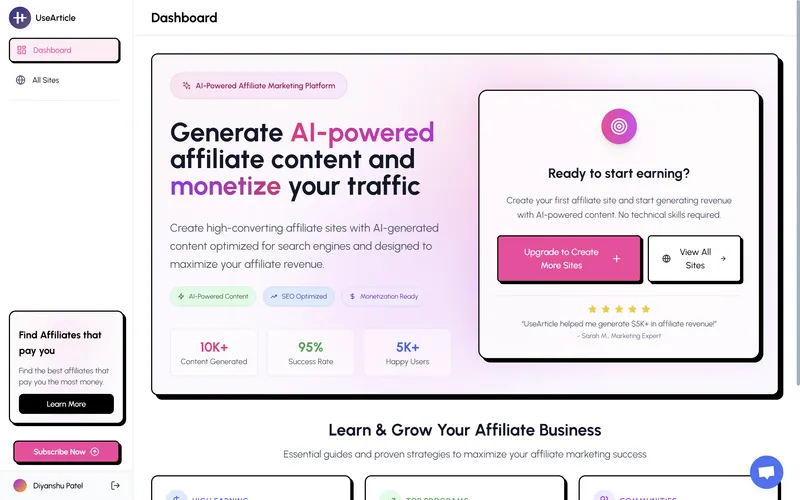
AI-powered content creation and management platform that helps teams produce high-quality articles at scale.
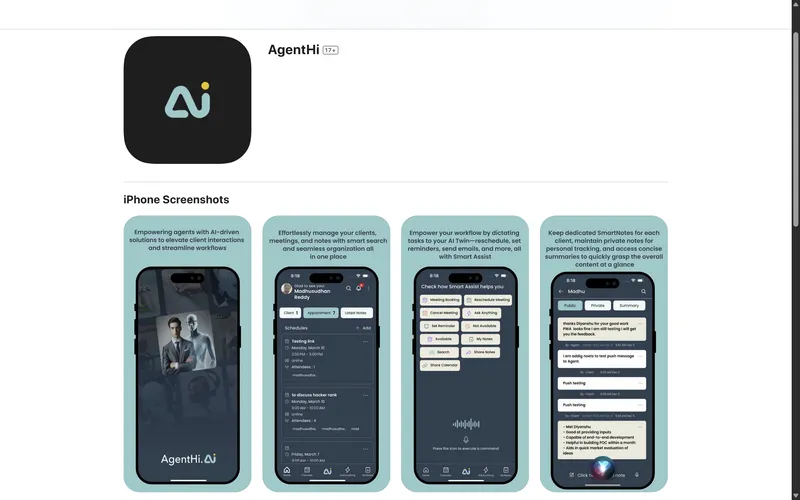
Intelligent virtual assistant that streamlines customer support and automates routine business tasks.
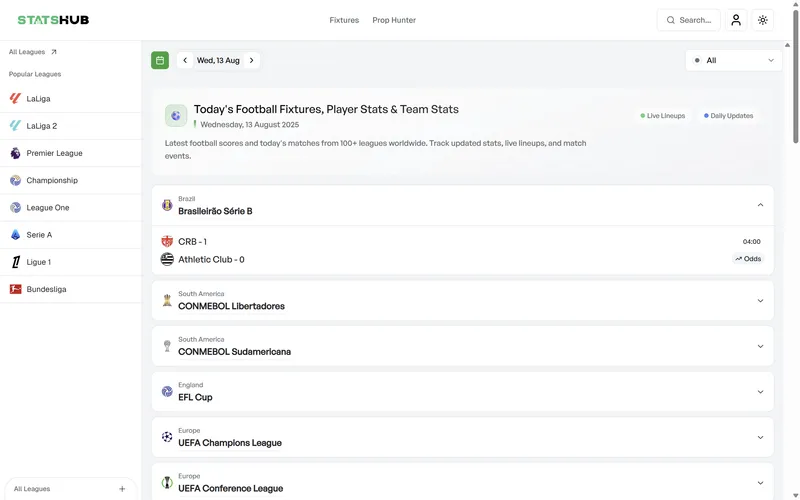
Comprehensive analytics dashboard providing real-time insights and data visualization for businesses.
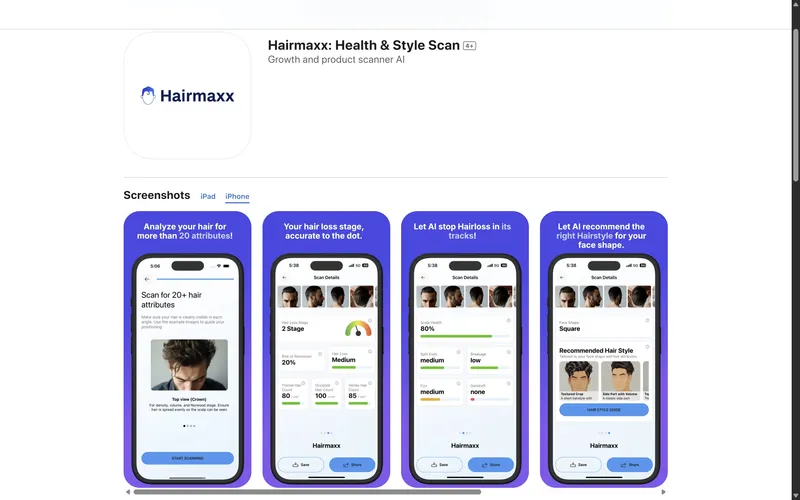
Personal fitness companion with AI-driven workout plans and nutrition tracking for optimal health.
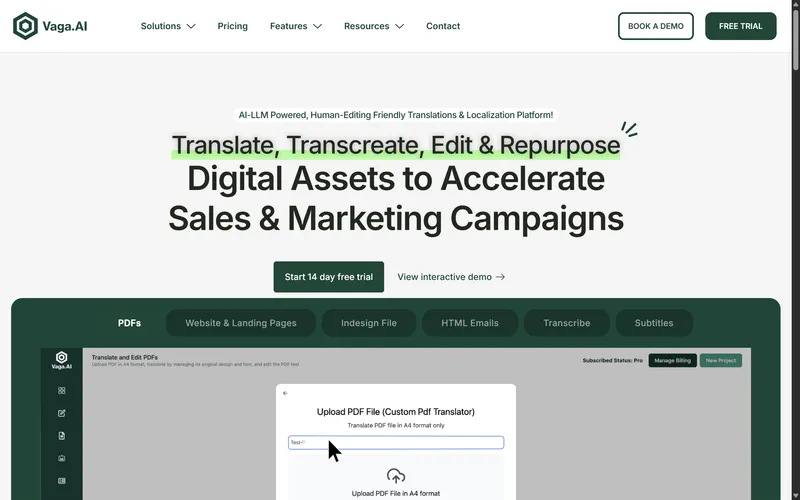
Smart travel planning app that curates personalized itineraries and local experiences.
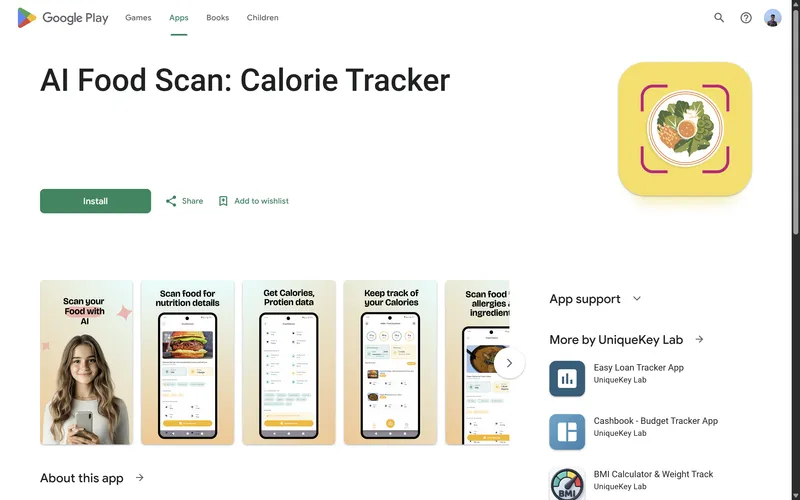
Nutrition analysis app that scans food items and provides detailed nutritional information instantly.
Job matching platform connecting talented professionals with their dream opportunities.
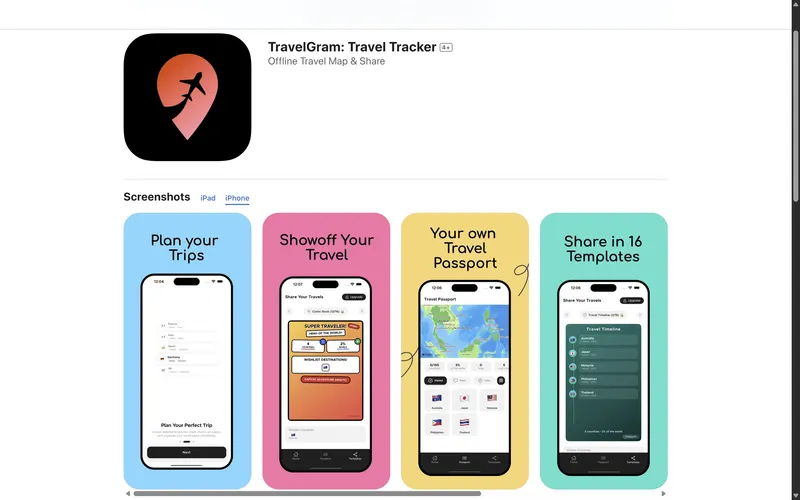
Social platform for travelers to share experiences, discover destinations, and connect globally.
Advanced sports statistics platform delivering in-depth analysis and performance metrics.
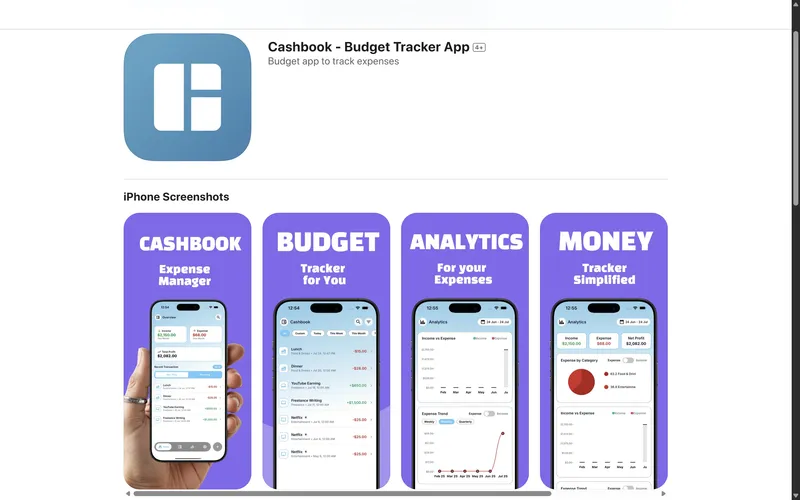
Simple expense tracking and budgeting app that helps users manage their finances effortlessly.
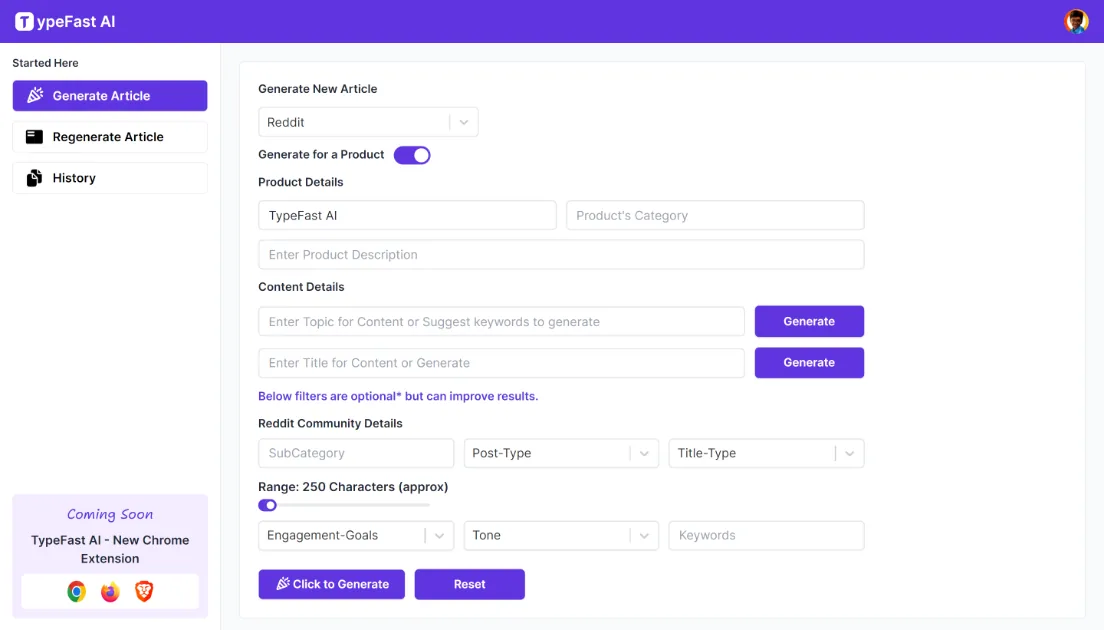
Typing speed improvement platform with gamified lessons and real-time performance tracking.
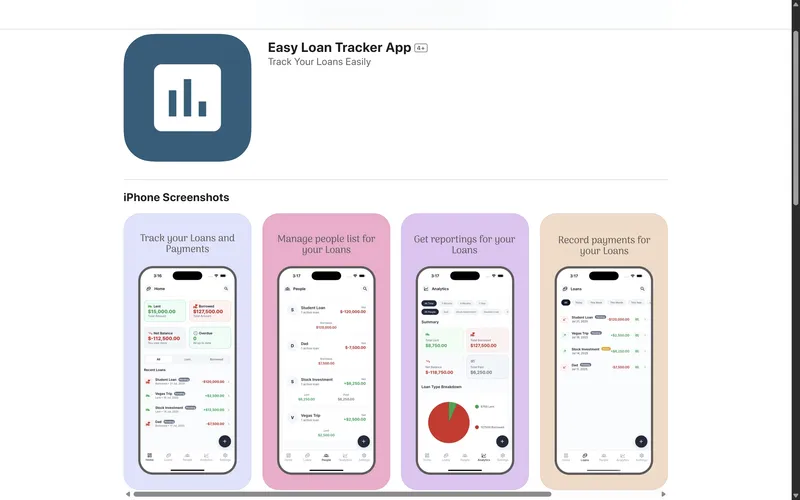
Streamlined loan management system that simplifies borrowing and lending processes.
Discover more services, technologies, case studies, and resources
Object detection locates and classifies objects within images and video: bounding boxes, class labels, and confidence scores, in real time or in batch. We build the full pipeline, from dataset labeling through model training to deployment on cloud GPUs or edge hardware, tuned to your specific accuracy and latency requirements.
Voice-first AI covers speech-to-text, text-to-speech, and the voice agents built on top of them: systems where the primary interface is a phone call or spoken interaction, not a text box. That means different architecture decisions than a chat product: streaming audio pipelines, turn-taking and interruption handling, telephony integration, and latency budgets measured in hundreds of milliseconds, not seconds.
Production-grade engineering for companies that have outgrown MVP-quality code. We rebuild critical systems for reliability, security, compliance, and scale: while keeping your product running.
Custom ERP/CRM platforms, secure integrations, RBAC, and scalable microservices tailored to complex enterprise workflows.
Schedule a complimentary strategy session. Transform your concept into a market-ready MVP within 2-3 weeks. Partner with us to accelerate your product launch and scale your startup globally.