
Text Classification
Intent detection, ticket routing, and content tagging using fine-tuned encoders or zero-shot classifiers.
Natural language processing covers the toolkit that turns unstructured text into structured, actionable data: classification, entity extraction, sentiment analysis, and semantic search built on embeddings. We build this independent of (or alongside) generative LLMs, choosing purpose-built models when they are faster, cheaper, and more accurate than a general-purpose chat model for a fixed, well-defined task.
The non-generative half of the NLP toolkit, applied where it beats a general-purpose LLM
Intent detection, ticket routing, and content tagging using fine-tuned encoders or zero-shot classifiers.
Named entity recognition and relation extraction that turns free text into structured fields.
Aspect-based sentiment analysis across reviews, support tickets, and survey responses.
Embedding-based retrieval with hybrid lexical and vector ranking for accurate, fast search.
Language detection, multilingual embeddings, and translation pipelines for cross-lingual products.
Labeled test sets and metric tracking to pick the right model, not just the newest one.
Production monitoring that flags accuracy decay and triggers retraining before it hurts users.
We don't reach for an LLM by default. When a fine-tuned classifier is faster, cheaper, and more accurate, that's what we ship.
Every model ships with a precision/recall report against a labeled holdout set, not a demo that looked good once.
Off-the-shelf models miss your product's jargon and edge cases; we fine-tune and validate on your actual data.
Language detection and multilingual embeddings are built in when your users aren't all English speakers, not bolted on later.
We don't reach for an LLM by default. When a fine-tuned classifier is faster, cheaper, and more accurate, that's what we ship.
Every model ships with a precision/recall report against a labeled holdout set, not a demo that looked good once.
Off-the-shelf models miss your product's jargon and edge cases; we fine-tune and validate on your actual data.
Language detection and multilingual embeddings are built in when your users aren't all English speakers, not bolted on later.
We've helped startups and enterprises worldwide transform their AI ideas into production-ready MVPs in 2–3 weeks. From fintech platforms to AI assistants, our global MVP development services have launched 18+ AI products serving users across the US, Europe, and Asia.
From content platforms and AI assistants to analytics dashboards and fintech solutions: see how we've transformed ideas into production-ready MVPs in 2-3 weeks across diverse industries. Each product launched successfully, serving users globally.
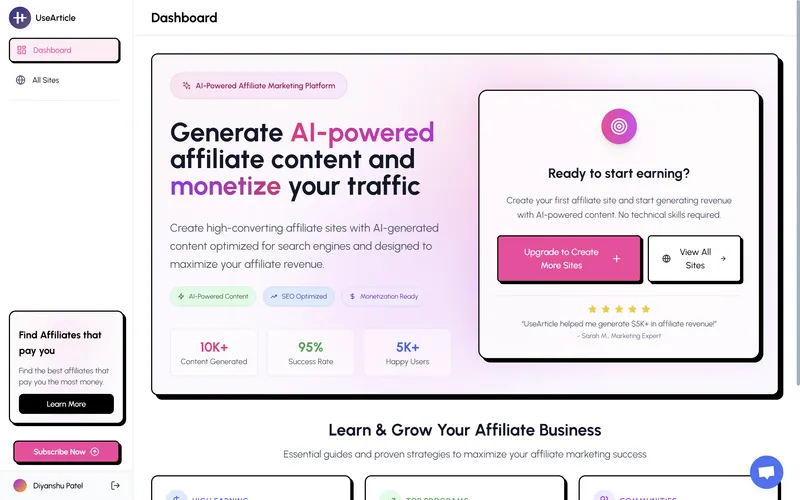
AI-powered content creation and management platform that helps teams produce high-quality articles at scale.
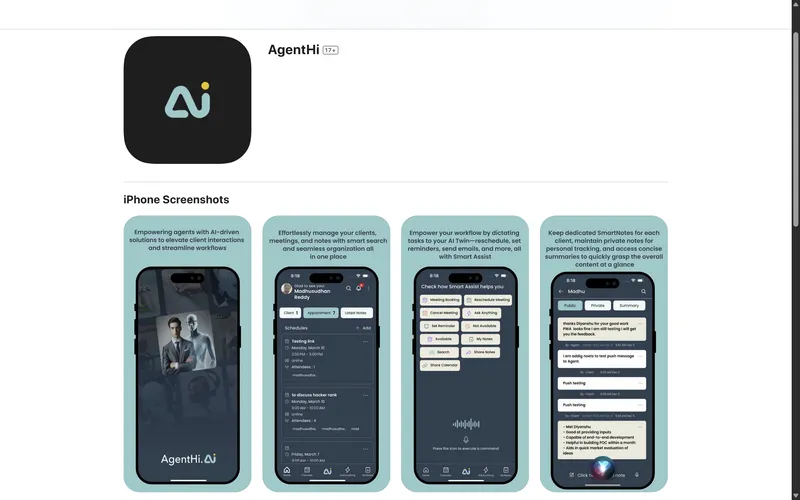
Intelligent virtual assistant that streamlines customer support and automates routine business tasks.
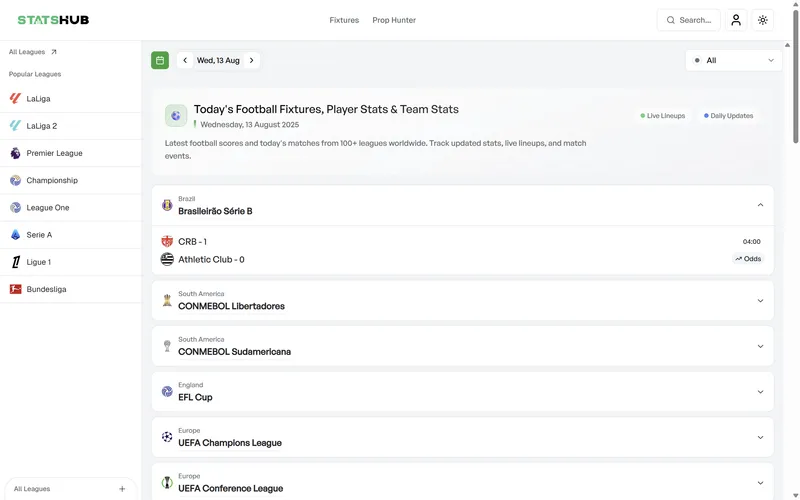
Comprehensive analytics dashboard providing real-time insights and data visualization for businesses.
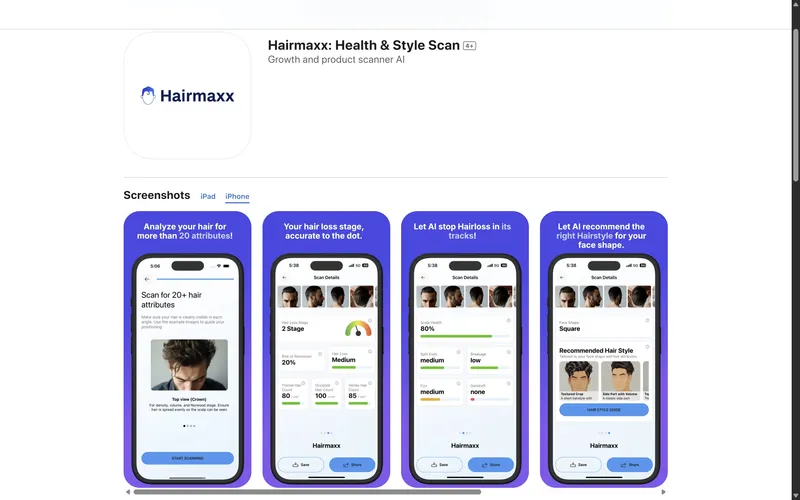
Personal fitness companion with AI-driven workout plans and nutrition tracking for optimal health.
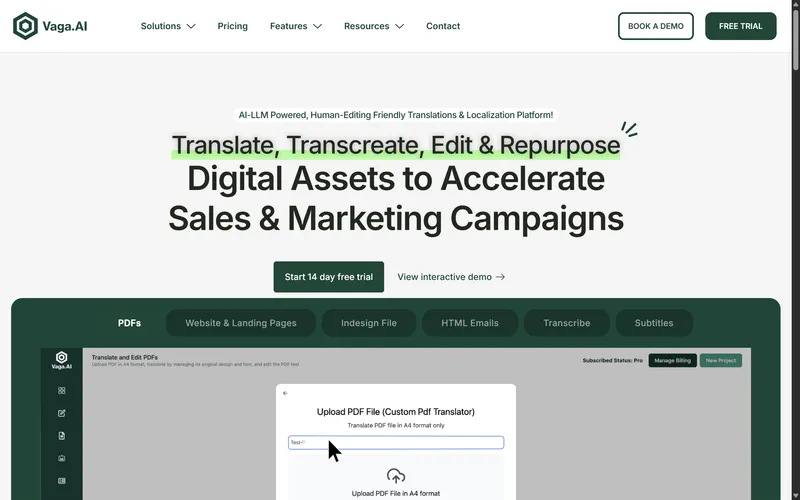
Smart travel planning app that curates personalized itineraries and local experiences.
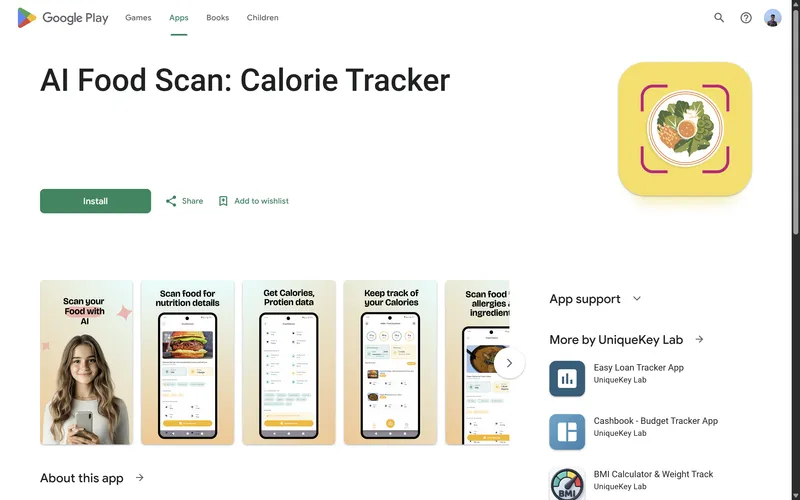
Nutrition analysis app that scans food items and provides detailed nutritional information instantly.
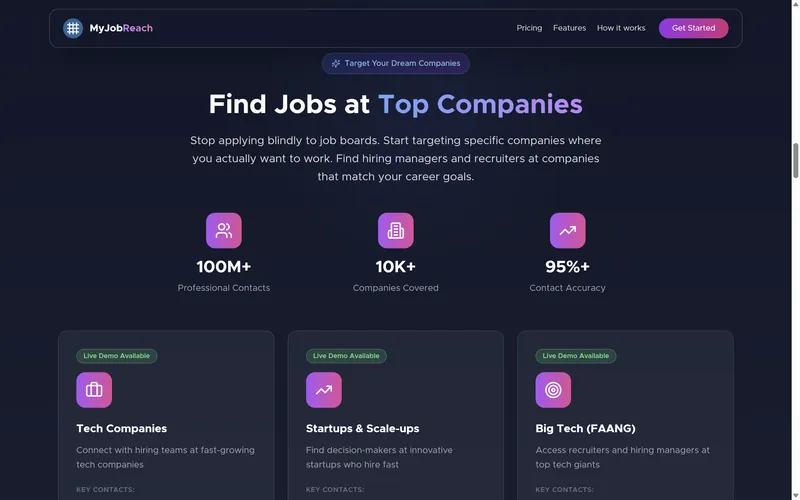
Job matching platform connecting talented professionals with their dream opportunities.
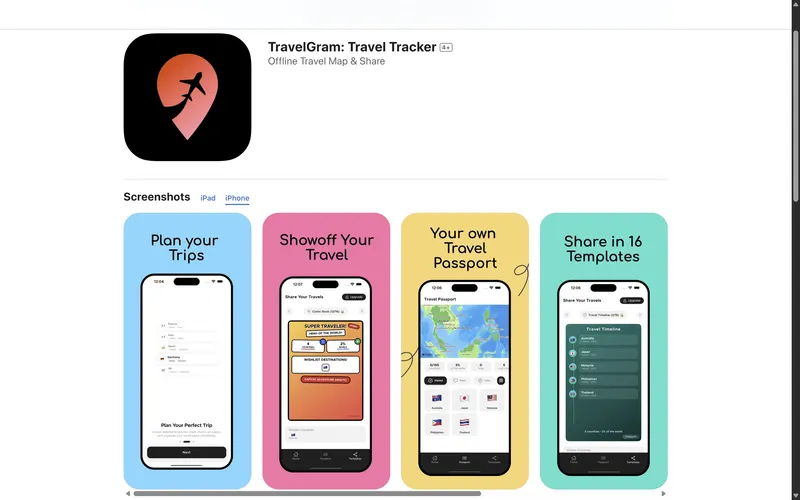
Social platform for travelers to share experiences, discover destinations, and connect globally.
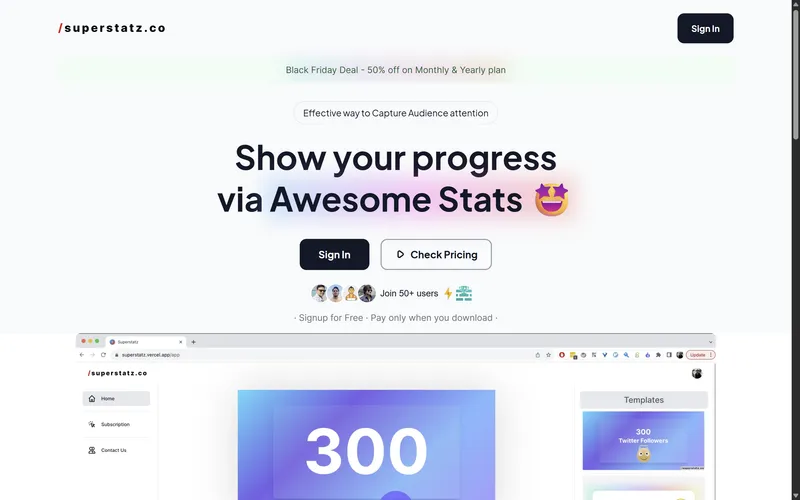
Advanced sports statistics platform delivering in-depth analysis and performance metrics.
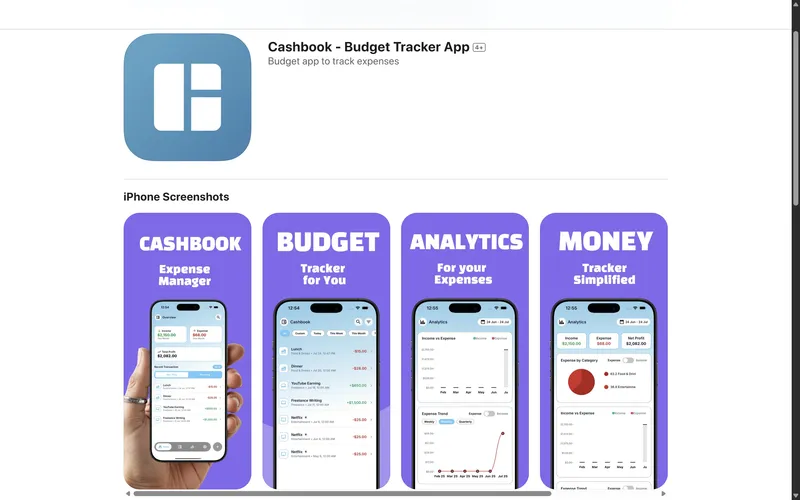
Simple expense tracking and budgeting app that helps users manage their finances effortlessly.
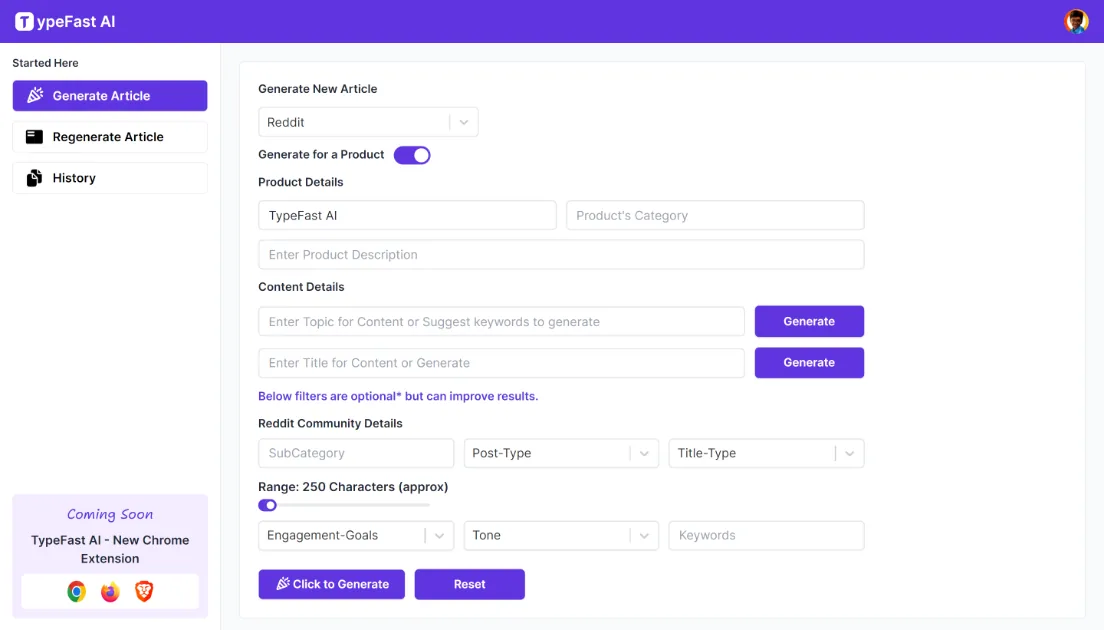
Typing speed improvement platform with gamified lessons and real-time performance tracking.
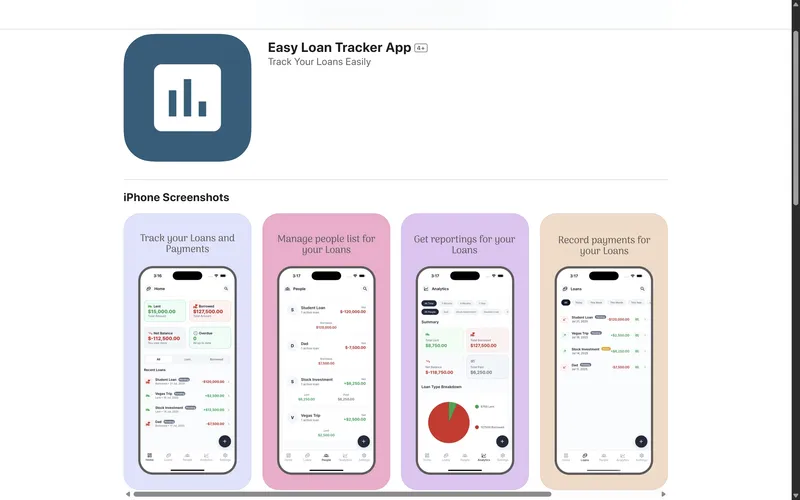
Streamlined loan management system that simplifies borrowing and lending processes.
Discover more services, technologies, case studies, and resources
Plug GPT-5, Claude Opus 4.7, Gemini 2.5, or open-source models into the products your customers already use. We design the gateway, the prompts, the eval suite, and the cost controls so your LLM features ship in weeks and stay reliable in production.
Intelligent document parsing extracts structured data, line items, totals, dates, parties, clauses, from invoices, contracts, forms, and unstructured PDFs or scans, combining OCR for layout and text recognition with LLM-based extraction for the semantic parts a rules engine can't reliably handle. Most production systems need a human-in-the-loop review step for anything below a confidence threshold, plus integration into whatever system of record the extracted data ultimately feeds. That covers the extraction pipeline itself; ERP or CRM system integration is scoped separately based on which systems are involved.
Object detection locates and classifies objects within images and video: bounding boxes, class labels, and confidence scores, in real time or in batch. We build the full pipeline, from dataset labeling through model training to deployment on cloud GPUs or edge hardware, tuned to your specific accuracy and latency requirements.
An SRE-style reliability hardening add-on for products that already have real traffic: monitoring, alerting, autoscaling, backups, and incident runbooks so the system stays up and recoverable under load. This is ongoing operational practice, not the one-time platform setup covered by Next.js Deployment and DevOps, and it's infrastructure-focused rather than feature-focused, unlike Post-MVP Iteration. It also isn't the full multi-region, compliance-driven program covered by Enterprise-Grade Engineering: this add-on is day-to-day reliability practice for a single-region product that needs to stay up, not a SOC 2 or HIPAA rebuild.
Schedule a complimentary strategy session. Transform your concept into a market-ready MVP within 2-3 weeks. Partner with us to accelerate your product launch and scale your startup globally.