
OCR & Layout Extraction
Text and layout recognition on scans, photos, and PDFs, including tables and multi-column formats.
Intelligent document parsing extracts structured data, line items, totals, dates, parties, clauses, from invoices, contracts, forms, and unstructured PDFs or scans, combining OCR for layout and text recognition with LLM-based extraction for the semantic parts a rules engine can't reliably handle. Most production systems need a human-in-the-loop review step for anything below a confidence threshold, plus integration into whatever system of record the extracted data ultimately feeds. That covers the extraction pipeline itself; ERP or CRM system integration is scoped separately based on which systems are involved.
OCR plus LLM extraction, with review and integration built in
Text and layout recognition on scans, photos, and PDFs, including tables and multi-column formats.
Structured-output extraction for fields too variable for rules or regex to handle reliably.
Extracting line items and totals from invoices and forms with inconsistent vendor layouts.
Confidence-scored review queues so low-certainty extractions get corrected, not silently accepted.
Automatic routing of incoming documents to the correct extraction template by document type.
Extracted data pushed into NetSuite, QuickBooks, SAP, or your system of record via API.
Field-level logs of auto-extracted vs. human-corrected data for compliance and quality review.
OCR handles layout and character recognition; LLMs handle the semantic judgment calls neither pure rules nor raw OCR can make. We use each for what it's actually good at.
Every extracted field gets a confidence score. Below your threshold, it goes to a human reviewer instead of silently writing bad data into your system of record.
Vendors change invoice templates without notice. We design extraction to degrade gracefully and flag the unfamiliar case rather than fail silently.
Extracted data isn't useful sitting in a JSON blob. We wire it into your ERP, accounting system, or CRM as part of the initial delivery.
OCR handles layout and character recognition; LLMs handle the semantic judgment calls neither pure rules nor raw OCR can make. We use each for what it's actually good at.
Every extracted field gets a confidence score. Below your threshold, it goes to a human reviewer instead of silently writing bad data into your system of record.
Vendors change invoice templates without notice. We design extraction to degrade gracefully and flag the unfamiliar case rather than fail silently.
Extracted data isn't useful sitting in a JSON blob. We wire it into your ERP, accounting system, or CRM as part of the initial delivery.
We've helped startups and enterprises worldwide transform their AI ideas into production-ready MVPs in 2–3 weeks. From fintech platforms to AI assistants, our global MVP development services have launched 18+ AI products serving users across the US, Europe, and Asia.
From content platforms and AI assistants to analytics dashboards and fintech solutions: see how we've transformed ideas into production-ready MVPs in 2-3 weeks across diverse industries. Each product launched successfully, serving users globally.
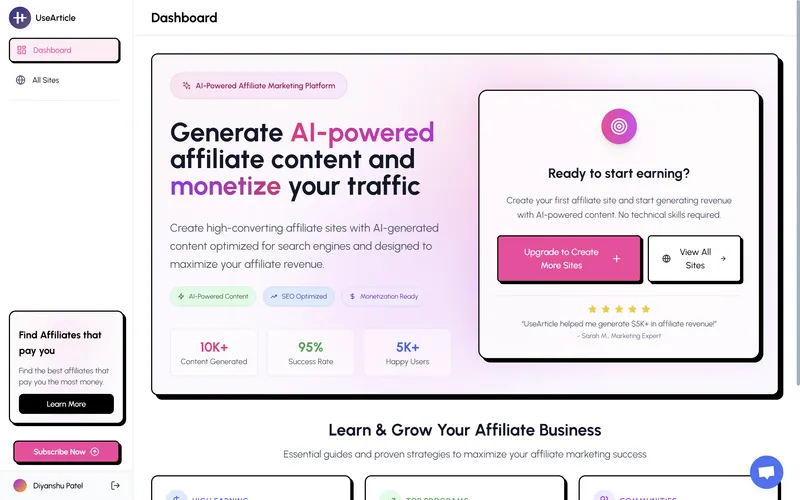
AI-powered content creation and management platform that helps teams produce high-quality articles at scale.
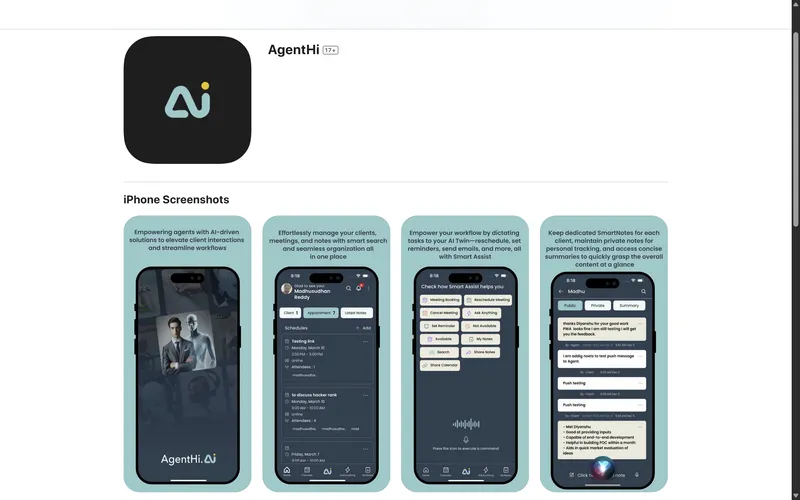
Intelligent virtual assistant that streamlines customer support and automates routine business tasks.
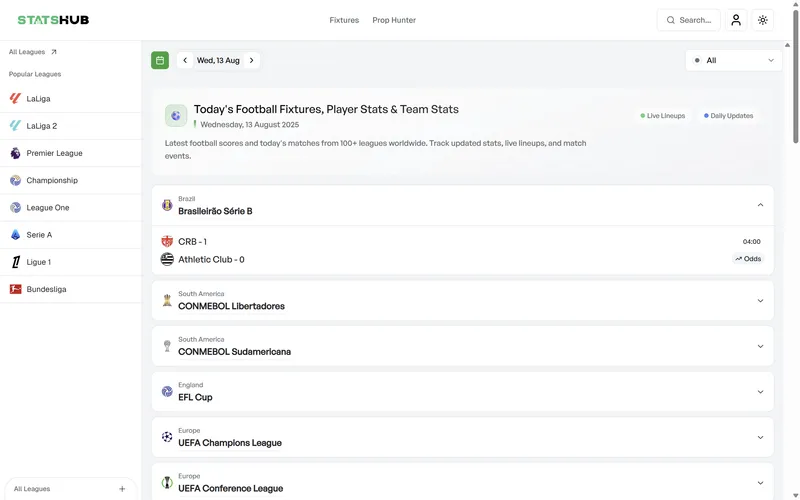
Comprehensive analytics dashboard providing real-time insights and data visualization for businesses.
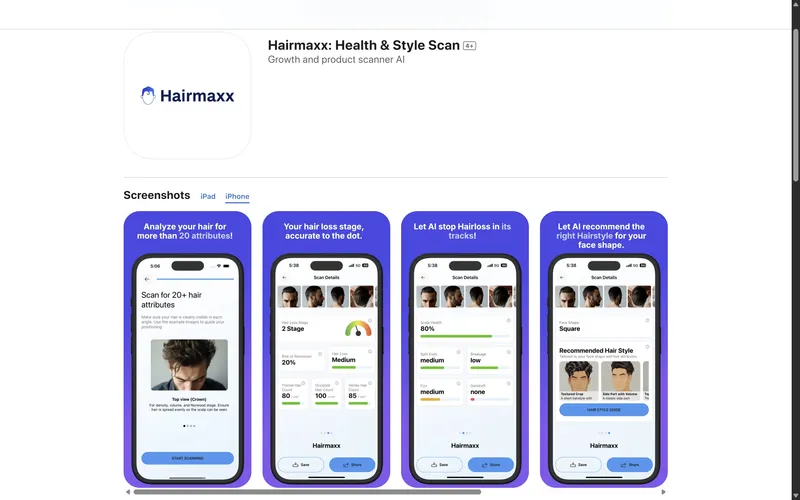
Personal fitness companion with AI-driven workout plans and nutrition tracking for optimal health.
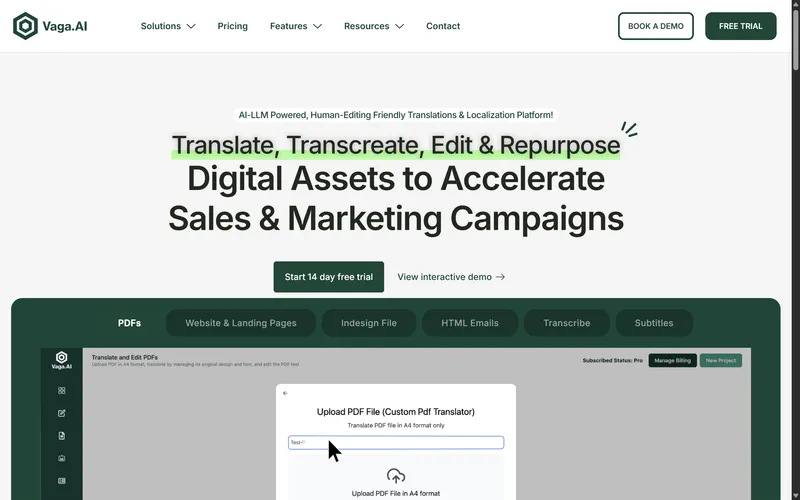
Smart travel planning app that curates personalized itineraries and local experiences.
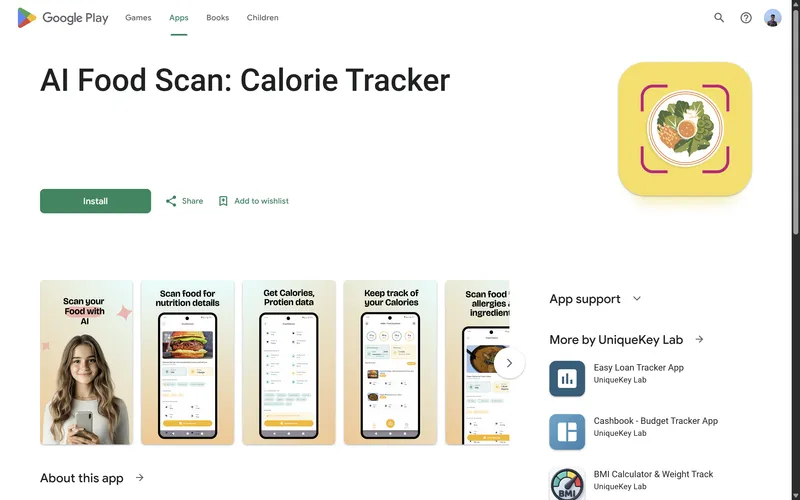
Nutrition analysis app that scans food items and provides detailed nutritional information instantly.
Job matching platform connecting talented professionals with their dream opportunities.
Social platform for travelers to share experiences, discover destinations, and connect globally.
Advanced sports statistics platform delivering in-depth analysis and performance metrics.
Simple expense tracking and budgeting app that helps users manage their finances effortlessly.
Typing speed improvement platform with gamified lessons and real-time performance tracking.
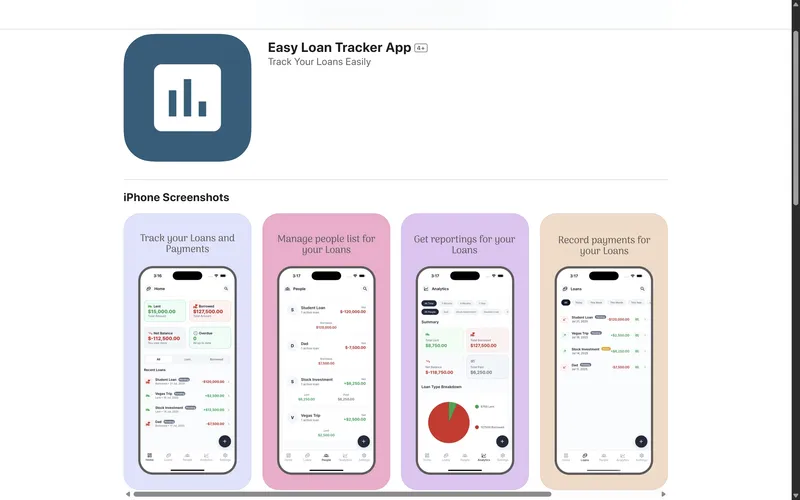
Streamlined loan management system that simplifies borrowing and lending processes.
Discover more services, technologies, case studies, and resources
Natural language processing covers the toolkit that turns unstructured text into structured, actionable data: classification, entity extraction, sentiment analysis, and semantic search built on embeddings. We build this independent of (or alongside) generative LLMs, choosing purpose-built models when they are faster, cheaper, and more accurate than a general-purpose chat model for a fixed, well-defined task.
Internal knowledge assistants are RAG-based chat interfaces built for employees, not customers: retrieval scoped to your internal docs, Slack history, Notion pages, and wikis, with permission-aware access so the assistant only surfaces what the asking employee is actually allowed to see. That access-control requirement, plus the need for an admin console and content freshness, makes this a meaningfully different build than a customer-facing support chatbot. A single-connector version can ship in that window; the full multi-connector, SSO-synced build described above typically takes longer, scoped during discovery.
Get investor-ready in 2 weeks. We build the metrics dashboards, analytics infrastructure, and KPI documentation investors expect to see during due diligence, so you never fumble a data question in a pitch.
Schedule a complimentary strategy session. Transform your concept into a market-ready MVP within 2-3 weeks. Partner with us to accelerate your product launch and scale your startup globally.